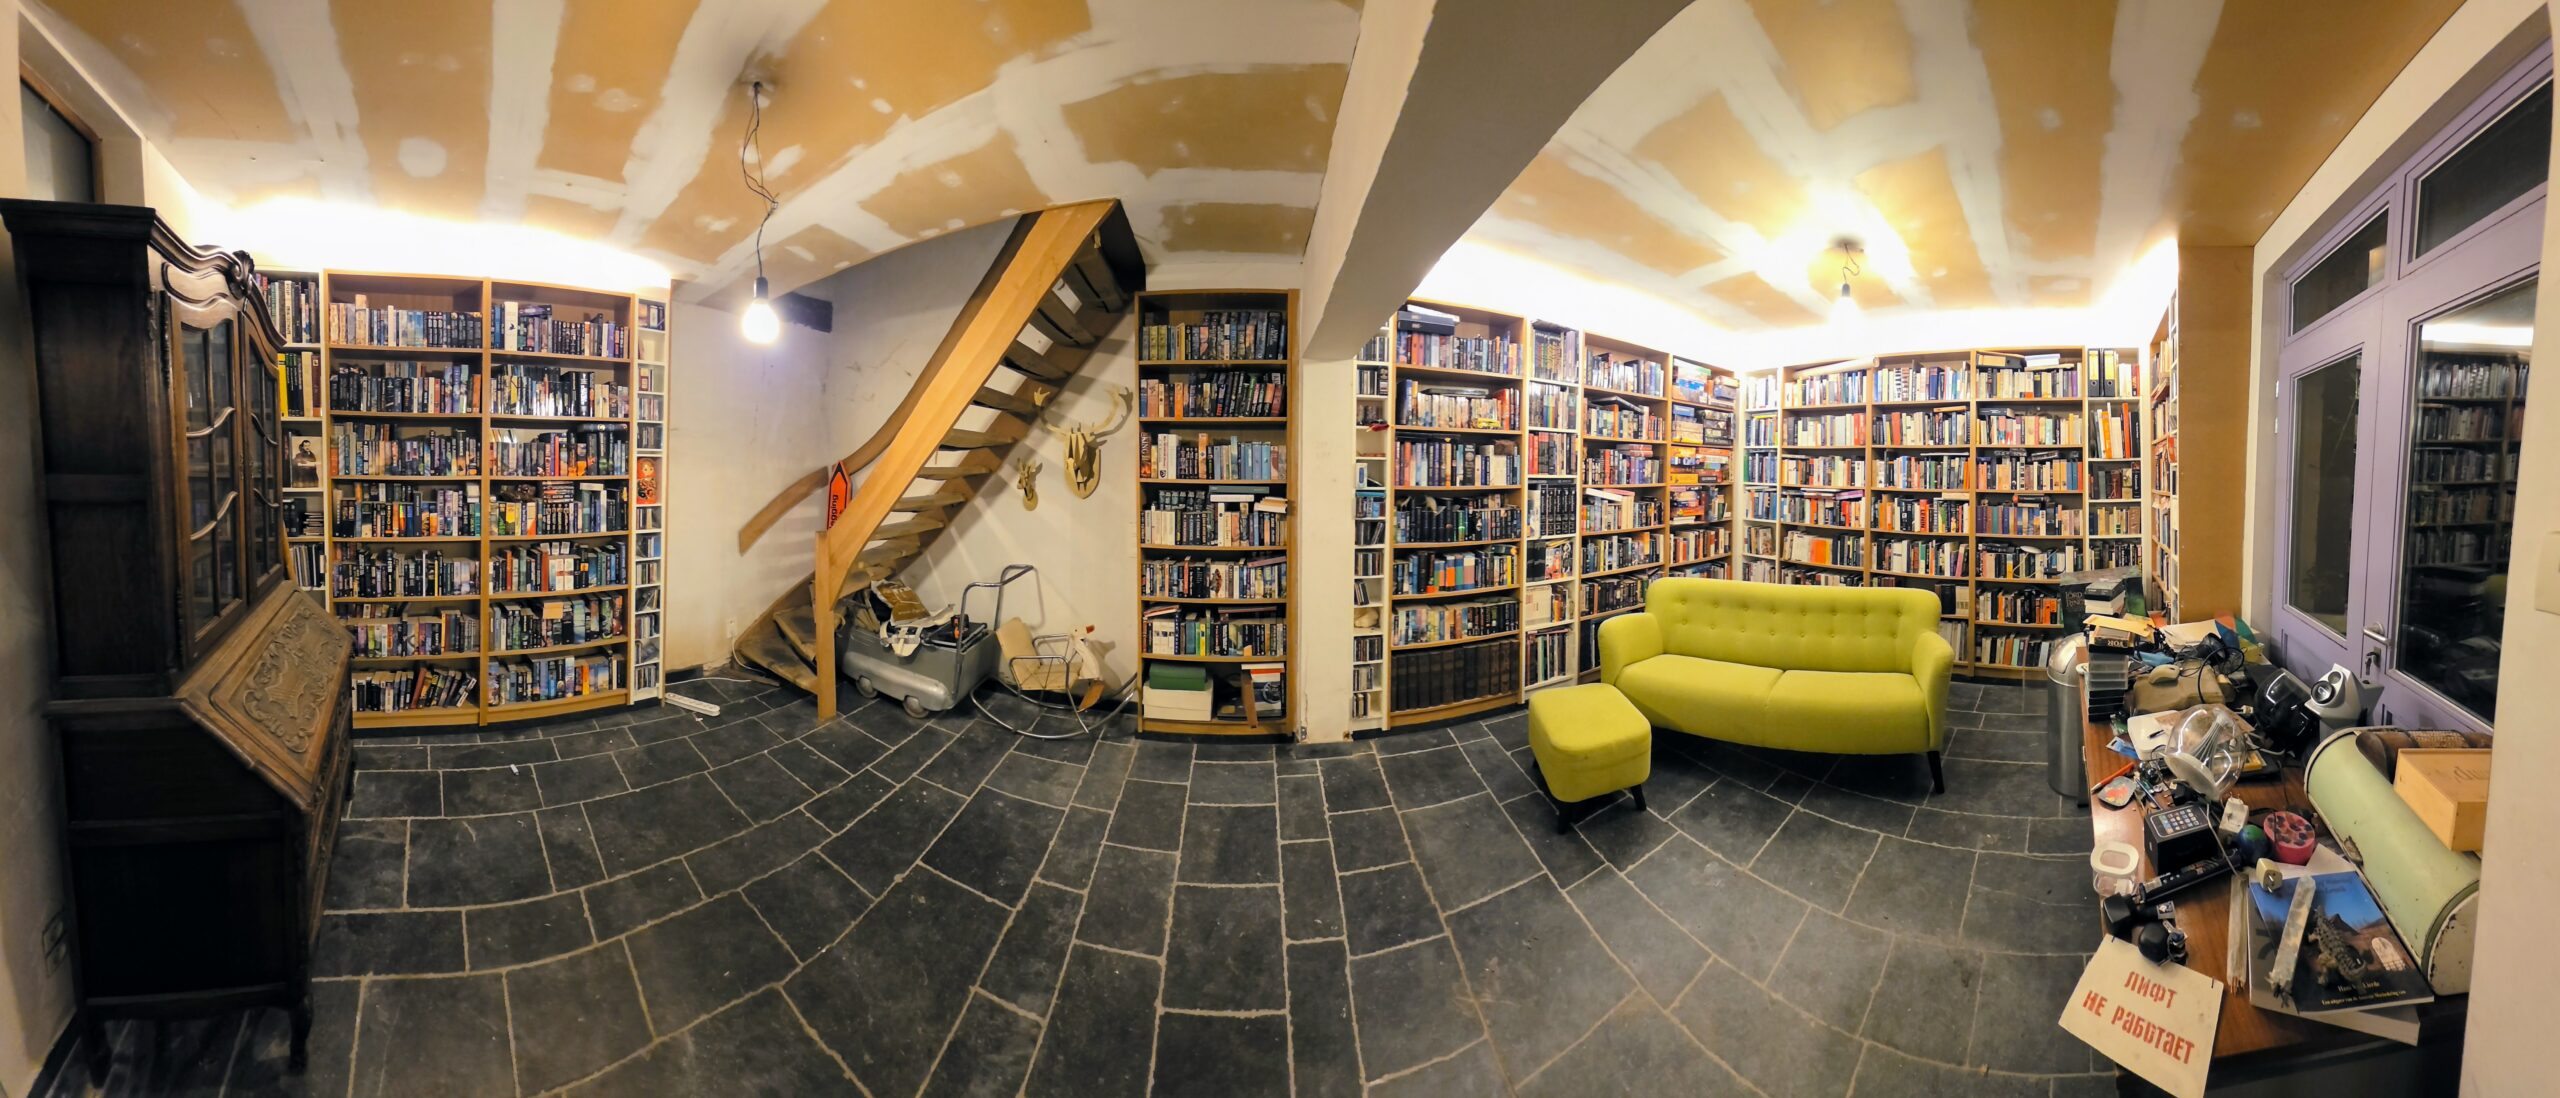
Ik was aan het sorteren in de boeken in het achterhuis, en ik had een reeks boeken die ik eigenlijk niet meer in de bibliotheek wou hebben.
In een doos steken en bij het oud papier zetten? Nee, dat doe ik uit principe niet. Proberen verkopen op het internet? Weinig plausibel, wie zit er te zoeken naar boeken die ik niet meer wil — voornamelijk oude pockets? Weggeven aan een school of een bibliotheek of zo? Ook weinig waarschijnlijk: zó goed zijn die boeken ook niet dat ze een plaats zouden hebben op een school, als ze die boeken zelfs maar al zouden aanvaarden.
In alle geval wou ik een lijst hebben van de boeken die ik weg wou doen, omwille van redenen.
Dus rijst de aloude vraag: hoe? Ik herinner mij dat ik, in de tijd dat ik nog 12.000 boeken had staan, speciaal een :CueCat had gekocht, via de mensen van Librarything, om de barcodes achteraan de boeken te lezen en zo toch een beetje rapper te kunnen gaan:
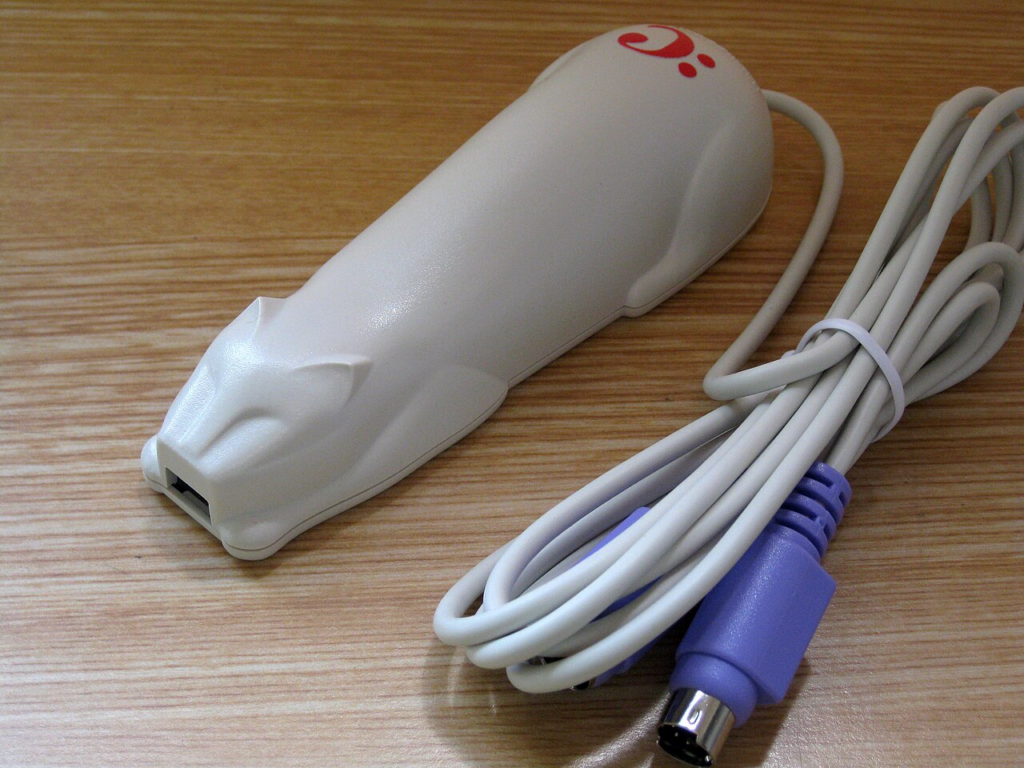
Ondertussen heb ik dat ding nog wel ergens liggen (ergens), maar het leek mij logischer om dat met de telefoon te kunnen doen.
Dus ik vraag aan Claude om mij zoiets te maken:
Build a PWA that does one simple task on my android phone: catalog books. Use the camera to scan in the isbn code of a book quickly look it up and add title, author, date, publisher, number of pages to a list. Use Open Library and/or Google Books for lookups — my Books API key is [….].
If the book cannot be found, let me take picture of the cover and look that up. If that doesn’t work, OCR the title and author and look for a match. As a last resort, let me manually edit the book.
I should be able to export the list of books in json.
Een paar minuten later had ik een werkende applicatie:
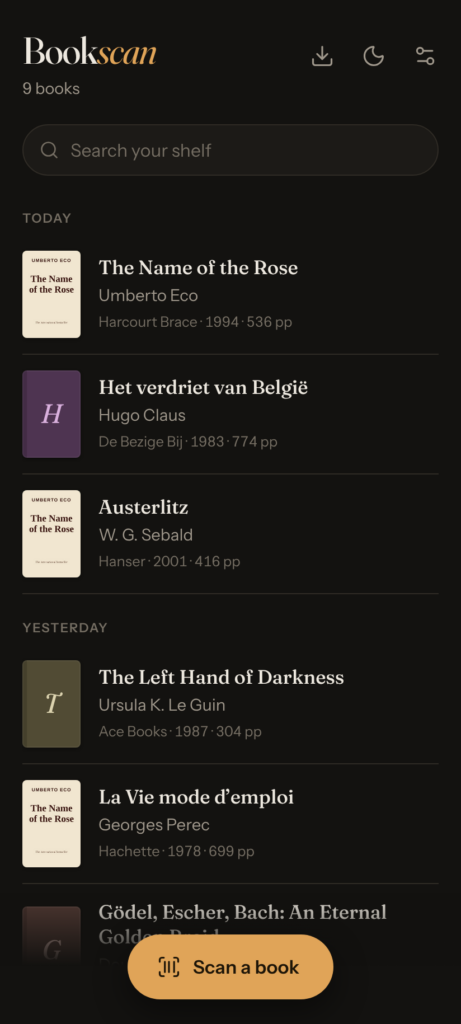
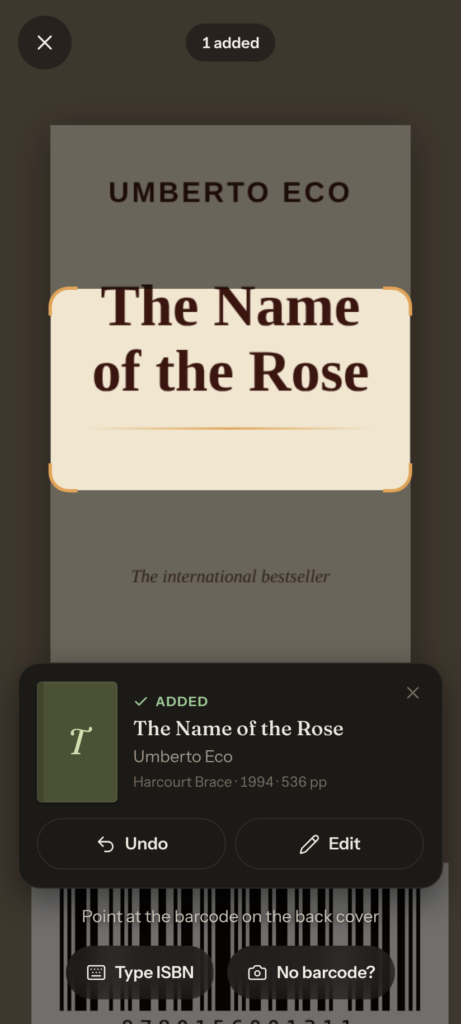
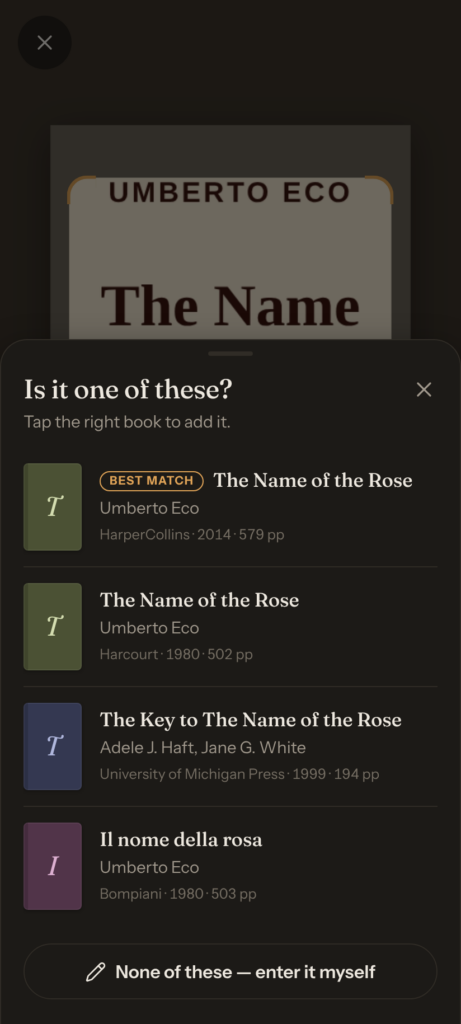
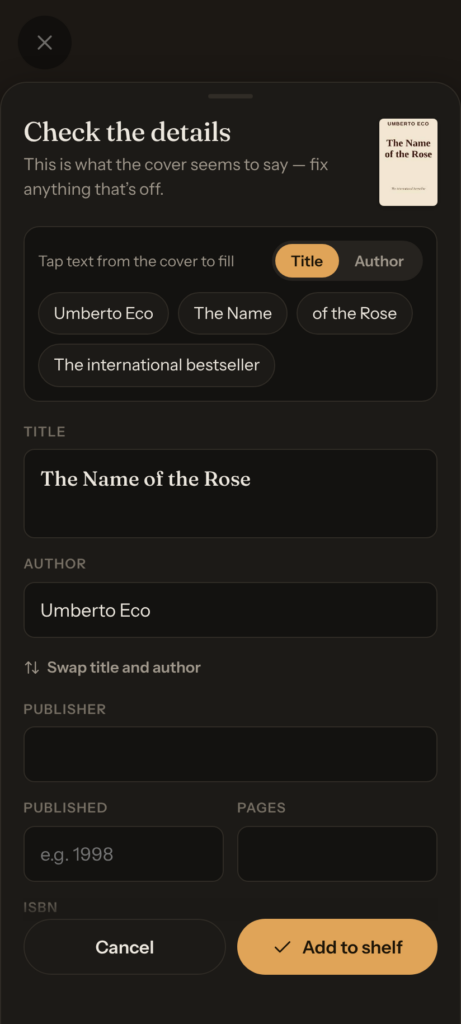
Ik heb een (sub)domeinnaam aangemaakt, de code daaropgezet en hopla ik kon eraan beginnen. Alles liep goed, dat scande in op géén tijd, maar dan ineens, oh no! deze barcode is hyperduidelijk, maar hij vindt toch geen boeken:
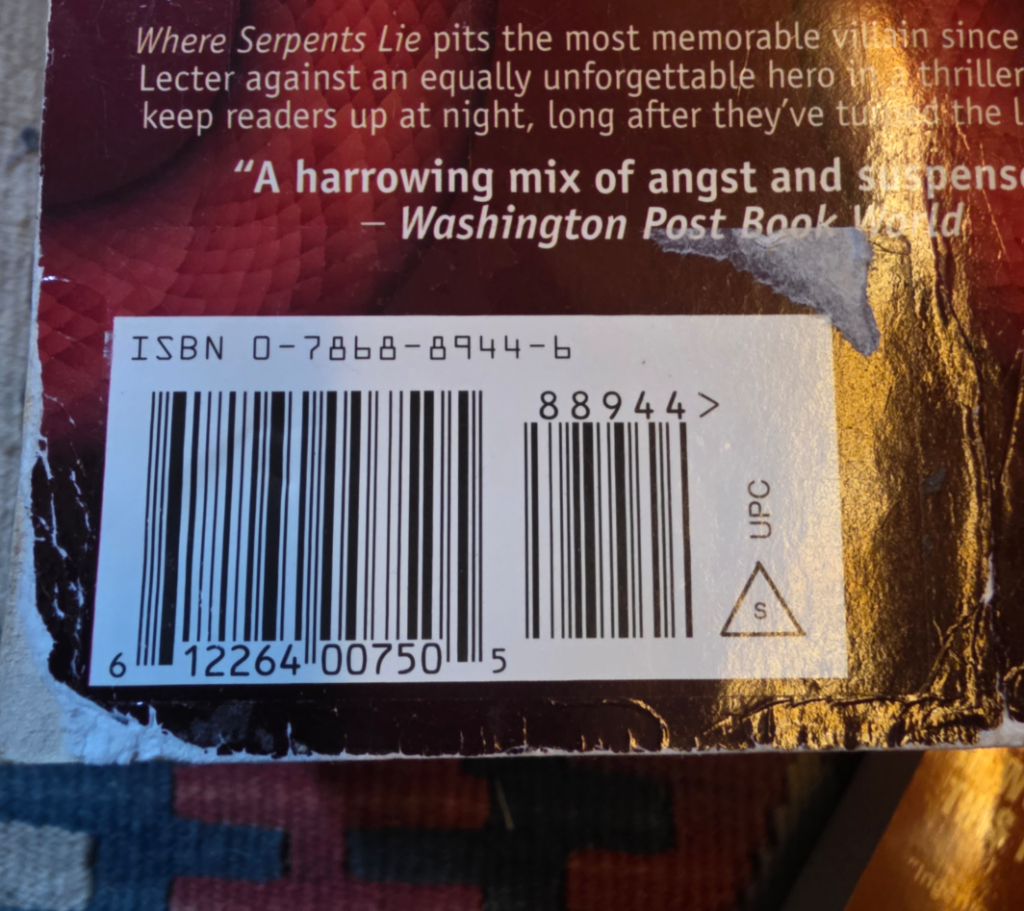
Geen paniek, zegt Claude:
The barcode is a UPC shop code, but the ISBN is printed right above it, so I’m setting the scanner to read that printed number automatically and testing it on your photo.
…
Close: the reader sees
ISBN 0-78bA-8944-b— that blocky font’s “6” looks like a “b”. Tuning the reading and adding checksum-guarded correction for those look-alikes.…
All regression tests pass and your book is now read correctly. Checking the two new screens, then pushing.
Ik heb nu een toepassing die preciés doet wat ik wil dat ze doet — snel, goedkoop, goed.
En dan bedenk ik, hang on. Dit is een zuiver client-side iets, alle data zit in de browser. Zou het niet veiliger aanvoelen als ik er ook een server-side compententje aan toevoeg om de gegeven bij te houden?
Optionally make the catalog persistent. If a user has a login and a password, they can save to the server and open from other places. Put this in a small Django app.
Vier minuten later:
Bookscan now has optional accounts. When you’re signed in, your shelf is also kept on the server, so you can open it on any other device. It’s live at [adres van de site]. I tested sync end to end locally; on the live site I’ve only checked that a wrong password gets a proper error, because no real account exists there yet.
To start using it, create your own account on the server (you’ll be asked for a password):
ssh -t -p [poortnummer] [server] 'cd /home/[foldernaam]/server && sudo -u [user] bash -c "set -a; . ./.env; set +a; venv/bin/python manage.py createsuperuser"'
Then sign in under Settings → Account. You can add more users at [adres]/admin. There’s no public sign-up, so only people you create an account for can sign in.How it behaves:
- When it syncs: about 1.5 seconds after any change, when the app comes back to the foreground, when the phone gets its connection back, and when you tap Sync now.
- Conflicts: each book syncs on its own, and if two devices change the same book, the newest change wins. Deleting a book on one device removes it on the others too.
- First sign-in: the books already on that phone are uploaded and merged with what’s on the server.
- Signing out: Sign out leaves the shelf on the device. Sign out & clear removes it from that device only, and won’t do it while changes haven’t reached the server yet.
- Without an account: the app works exactly as before.
- Login protection: after 10 failed sign-ins in 15 minutes, further attempts are blocked for a while.
In the code:
- Server: the Django app is in server/. The sync logic is in server/shelf/views.py, with 8 tests in server/shelf/tests.py, all passing.
- App: the sync code is in app.js. I bumped the service worker’s cache version, so installed copies will update, and it no longer caches the server’s pages.
- README: README.md now covers local setup and the deploy commands.
On the VPS:
- A gunicorn service,
[servicenaam], runs the server on port [poort], with its secret key in server/.env.- nginx passes
/api/and/admin/to it, and blocks public access to/server/.For local development there’s a launch config in .claude/launch.json. A local-only test account is saved in server/.dev-credentials, which git ignores.
En hopla, dat doet helemaal wat ik wil. Ik kan op mijn telefoon scannen, en dan op mijn desktop verder bewerken.
En dan bedenk ik, hang on, wat als ik hier meer boeken zou insteken? Gelijk de boeken in mijn bibliotheek, boeken die ik uitgeleend heb en zo?
En dan bedenk ik, hang on, ik heb een boekenwebsite en een manier om de boeken daar te editeren, en ik ben daar eigenlijk niet 100% content van. De bron van alle informatie daar zijn markdownfiles in een github repo, en om dingen aan te passen moet ik die files wijzigen en dus heb ik daar ook ene tooltje voor gebouwd, waarmee ik ook beoken op de lijst van te lezen boeken kan zetten en zo — maar ’t is allemaal wat clunky.
I want to expand this be a website with lists of books: books to read, books I have read, books I am reading, books that are in my library, books I have lent out, etc. A book can be on more than one list, but some lists are exclusive (e.g. to read / reading / read).
In the longer run I want to integrate this with my books website (boeken, at boeken.tsuk.org,, repo mvuijlst/boeken) and my book editing app ([naam], at [url], repo [repo]) — those two roughly do what I want them to do, but the editing cycle is very clunky. I want to keep the site at boeken.tsuk.org, but I would like he new integrated site/app at folio.yusupov.cloud. Give me a recommended path to get to this.
Enige tijd later zitten er lijstgen in het ding:


En Claude is above and beyond gegaan:
What the lists do
- Standard lists: Library, To read, Reading, Read and Lent out. Edit lists adds, renames, reorders and deletes them.
- Either-or sets: lists in the same set exclude each other, so putting a book on Read takes it off To read and Reading. Library and Lent out stand alone and combine with anything.
- Notes: a list can ask for a note per book. Lent out asks “Lent to”; the note shows on the book and is searchable.
- Scanning onto lists: a pill at the top of the scanner says where scanned books go (the open list, or your last choice). Scanning a book you already have puts it on those lists too.
- Navigation: each list has its own address (
#/list/read). Lists are a sidebar on a wide screen and a row of tabs on a phone.- Sync and export: lists sync through the Django server alongside the books, and the JSON export includes them.
….en heeft hij een plan:
The clunky part of the editing cycle is that every edit is a Markdown commit, a push and a 1–2 minute build. My recommendation:
- Folio is this app, renamed, at folio.yusupov.cloud, with its database as the place you edit. Saves are instant.
- Import boeken’s posts into Folio as books with reads: status becomes the list, plus rating, review, progress, series, authors and cover. The list ids
to-read,readingandreadalready match boeken’sstatus:values.- boeken.tsuk.org stays a static Hugo site. Folio publishes to it in the background by writing the same Markdown into
mvuijlst/boekenand pushing. Visitors see no change and URLs stay put.- [oude editeertool] retires once Folio covers what it does: progress updates, the review editor, AI intake and covers.
Ik ben het daarmee eens, en geef nog wat extra input: doe de zaken offline-eerst, met een sync die vanzelf zijn werk doet; maak het allemaal direkt maar tweetalig EN/NL; hernoem nu maar al alles naar de nieuwe naam — bookscan dekt de lading niet meer; pak de reviews vanop boeken.tsuk.org en voeg die ook toe aan de nieuwe app.


Voilà, een werkende applicatie.
Maar niet naar mijn goesting. Het ziet er allemaal te bruin uit, en te AI-achtig. Ik wil tinten van paars (dark mode) en beige (light mode), en ik wil met wat frissere kleuren werken, en ik wil er vooral veel meer dingen insteken die mijn leven aangenamer gaan maken.
Dus ik brainstorm wat over en weet (ironie, met een andere AI) tot ik een logo heb waar ik content van ben:
En dan schrijf ik wat ik wil (onder meer do not use those stereotypical divs with one rounded coloured corner, they look much too AI), en ik stuur bij tot ik heb wat ik wil – dingen zoals meer contrast, andere kleurencombinaties, of specifieke feedback zoals dit:
- I am not sure red is a semantic good fit for “books I have read”
- lose the italic ‘io’ in the logo, it reeks of AI
- border-radius throughout is too large, this too gives me a “designed by AI” feel.
- the buttons are incredibly present in dark mode; can we tone them down a bit?
- now the app is much more than it initially was, the huge “scan a book” button feels out of place — I think “add a book” is a better option, with an immediate choice to scan or add in a different way
- there is no path to the AI search from the “scan a book” flow — it seems logical that if I don’t have an ISBN code I should be able to add a book using an AI search
- improve cover recognition — it is really basic now, with very bad OCR. Use Google Cloud Vision to find the book’s information. I have enable Vision aPI for this application
En dan heb ik enige tijd later wat ik wou:


Voilà, applicatie klaar. Helemaal af.
En dan bedenk ik, hang on. Ik wil eigenlijk ook filters. En de manier waarop covers toegevoegd worden is eigenlijk niet naar mijn goesting. En ik maak foto’s van boeken die niet op het internet staan maar die staan er dan scheef op, ik wil die kunnen rechttrekken. En ik wil eigenlijk ook kunnen exporteren in een standaardformaat. En ik wil een bulk edit kunnen doen.
En de kleuren zijn nog niet helemaal in orde. En de filter moet sticky staan. En. En. En.


Zo. HELEMAAL KLAAR.
….maar dan bedenk ik, hang on, er zit een informatiearchituraal helemaal verkeerde kronkel in mijn toepassing: ik heb sommige boeken dubbel, en soms zelfs driedubbel. Er zijn boeken die ik twee keer op papier heb, één kopij die weg mag en één die ik wil houden, en waar ik hetzelfde boek ook in ebook heb gelezen en zelfs boeken die ik zowel op papier gekocht heb als als audioboek, en ook nog eens op mijn Kindle heb staan. En dan zijn er ook nog vertalingen — ik heb zowel De geverfde vogel als The Painted Bird staan, en minstens vier versies van de Odyssee.
Dat zou dus de doodsteek geweest zijn voor een dergelijk project tot voor zeer recent: een totale refactoring van zowel een app als een boekenweblog dat ervan afhangt, met import- en exportformaten, en allerlei erop en eraan.
Nu?
I think we need to separate the work (e.g. Equal Rites by Terry Pratchett) and the copy (e.g. a hardcover, two softcover editions, an audiobook with extra ‘authors’, an ebook). The way we treat different copies of books now is muddled. Note that a book can also be translated, so we may have both The Painted Bird and De geverfde vogel by Jerzy Kozinski.
Think carefully where to put the data: the work holds writers, series & number, categories, tags, title; the edition can hold a different title, language, format, cvover, publisher, year, pages, ISBN, possible extra authors (e.g. translator, narrator), lists(s) the edition belongs to; a read holds the edition I read, dates, progress, ratings, reviews. If I have a book in two languages, that is one work with two editions.
If this change is done, it would need to be very carefully executed so we keep excellent UX: multiple editions will be the exception to the rule, so single-edition books must look exactly as they do now. Scanning mlust remain a one-step operation — you can suggest “same book as [other edition]?” but must not block on this.
Give me your opinion first, please.
Claude geeft mij lang niet altijd gelijk, maar hier wel:
Yes, I think it’s a good idea. I’d do it in the two levels only: a work and its editions, with each read pointing at one edition.
Why it feels muddled now. The same situation is modelled three different ways, depending on how the book arrived:
- A reread in another form is an edition tucked inside the review.
- A version (the audiobook of an e-book you have) is a separate book with a
versionOfpointer to the other one.- Another copy is a separate book with no link at all.
On top of that, a book’s own cover, format and people are really those of its latest read. So “what is this book” depends on what you read last.
Klinkt alsof we op dezelfde golflengte zitten, dus ik zeg Claude Fable 5.2 “Design it and make a plan that Opus 5.5 can execute.” en dan vertrek ik naar mijn werk.
Tegen dat ik thuiskom, staat er een lang document klaar met op het einde een stuk of negen vragen voor mij om te beantwoorden. En dus kan ik Open 5.5 in gang zetten met dit:
Implement
docs/work-edition-plan.md. Here are answers to the questions in (9).
- 1-5: OK with the default
- 6: edition / kopie; Add another edition / Nog een kopie toevoegen; Make it a book of its own / Apart boek van maken — the rest is OK
- 7: if I reread a book in a translation, it should be a second page on the booklog but not a second book.
Hij heeft er eten en drinken aan, en geeft mij na een klein half uur dit rapport:
Stages 0 to 4 of the plan are built as version 2.0.0 on the branch
works-and-editions, in four commits. Nothing is pushed or merged, and nothing has touched production.Your answers, applied
- 1–5: built as the plan’s defaults.
- 6: in Dutch an edition is a kopie: Kopieën, Nog een kopie toevoegen, Apart boek van maken, Apart houden, Samenvoegen met een ander boek. A second copy of the same edition stays Nog een exemplaar. The older Dutch sentences that said editie now say kopie.
- 7: reading a book again in a translation adds a reread page to the same book in the booklog, not a second book. Giving that page the translation’s own title is stage 5, which isn’t built.
How it was checked
- Tests: 138 server tests and 26 new app tests pass. The app and the server convert an old record the same way; 14 shared examples taken from your real data prove it.
- Rehearsal: on the local database, against a copy of the booklog that cannot push. Publishing lists the same three books with the same files before and after the conversion. Importing after it changes nothing, twice, and a second conversion writes nothing.
- In the browser:
- A one-edition book’s page and form are identical to 1.29.0, apart from the new Add another edition link and Combine with another book… at the bottom of Edit details.
- Filters pick the right edition for each row.
- Scanning another edition’s ISBN attached it to the book without asking; Keep separate and Another copy both worked.
- Combine and Undo, and Make it a book of its own and Undo, each left the records byte-identical.
- A read e-book with an audiobook on To read appears under both To read and Read, and would publish exactly one new post.
- Independent review: a separate reviewer found seven bugs, all fixed. The two that mattered most:
- an edition being edited lost its changes when a sync arrived;
- Keep separate threw away edits made after the add.
Where the build departs from the plan
These are listed in a new section 10 of docs/work-edition-plan.md. The ones you’d notice:
- Not after all: a book you’ve read before that is back on To read offers Not after all (back to Read) instead of Drop. Drop would have deleted the book with all its reads.
- Possibly the same book: two titles match only when one is the other plus a subtitle. Comparing the parts before the colon made all the B.P.R.D.: … volumes one book.
- Describe it: a proposal with no ISBN that matches a book you already have in the same format still says Already on your shelf, rather than becoming a second edition.
Not done
- Production rehearsal: this needs a copy of production’s database from you.
- Cut-over: section 8 of the plan, which only you start.
- Stage 5: not built.
- Not tried in the browser: photographing a cover and Describe it, because there’s no camera or assistant locally; and two devices editing at once.
Ik geef nog wat feedback, tot het eruiziet zoals ik wil dat het eruitziet en het zich gedraagt zoals ik dat wil:


En dan geef ik hem een kopie van de database om op te testen, dat geeft geen problemen, en dus zeg ik dat hij aan de cut-over mag beginnen. Hij maakt duidelijk wat dat zal worden:
The cut-over is ready to run: docs/cutover-2.0.md has every step as a command, with the output the production rehearsal predicts. I haven’t changed anything on the server.
Nothing in the deploy should surprise: there are no new database migrations and no new requirements. The branch already contains GitHub’s
main, so merging it is a fast-forward with nothing to resolve.The steps:
- Make sure every device has synced (Settings → Account shows nothing waiting).
- Stop the booklog timer.
- A publish dry run must show nothing waiting.
- Back up the database as
db.sqlite3.before-works-<date>beside the earlier copies.- Merge into
mainand push, which deploys 2.0; then check thatapp.jssays 2.0.0 andworks.jsloads.- Convert the shelf: first a dry run, which should report 2,102 books, 2,120 editions, the one Fire & Blood merge and nothing waiting. Then for real, then once more, which should write nothing.
- Import from the booklog, then do a publish dry run. Only Fire & Blood, and perhaps Grim Leaper, may be updated, and nothing may be waiting. Anything else updated means stop and look.
- Start the timer and watch two runs; no new commit from Folio should appear in the booklog.
- On each device, check the app now says 2.0.0.
The runbook starts with a small
folioshell helper that runs management commands asdjangowith the app’s settings, the way the timer’s service does. It also covers going back:
- Stop the timer and the sync server.
- Restore the backup and remove the
-wal/-shmfiles beside the database.- Revert
mainto before the merge and push.- On each device, Sign out & clear and sign in again.
From the moment of the deploy, copies of the app that haven’t updated get “out of date” when they sync. The booklog commands refuse to run until the conversion is done, so the steps can’t run in the wrong order.
One leftover: the deploy never deletes files, so the removed
set_papercommand stays on the server. It’s harmless, and the runbook gives the line to remove it.The runbook is committed on
works-and-editions(6 commits, not pushed).
Mijn database is nog niet zó uitgebreid, maar dit soort dingen is in het echt enorm griezelig. Ik moet niet denken aan de dagen en weken die ik in mijn leven gespendeerd heb aan het ordentelijk doen verlopen van dergelijke grote refactorings.
Nu was dit — zes minuten en geen verrassingen.


En hopla:


Zo. Voorlopig nu echt definitief helemaal klaar.
Dit is wat het doet op telefoon:
Oh maar hang on ik zie nog een paar dingen die ik wil veranderen — er staat bij nader inzien teveel nonsens op het scherm dat een gebruiker afleidt van de hoofdtaak.
Euh, ik zet het op een lijst met dingen te doen. 🙂
⁂
MAAR WAT IK DUS WOU ZEGGEN. Ik heb dit gemaakt in een paar sessies van hier en daar eens een uur. Als ik dit van nul zou moeten maken en ik heb niets anders te doen, denk ik dat ik er een week of vijf zes mee bezig zou zijn — om tot iets te komen dat zeer ongetwijfeld niet echt stevig in mekaar zou zitten.
En ik weet van UX en UI af, ik heb veel ervaring met Django, dit is niet mijn eerste PWA, mijn eerste editeer-hier-en-synchroniseer-naar-daar-toepassingen waren gebouwd met Delphi op desktop en een zelfgemaakt framework in ColdFusion en java op de backend — om niet te spreken van het enorme voordeel dat ik het doelpublien en de ‘business’ en de product owner ben.
Dit laten maken door een klein team (UX/UI, backend, frontend, PM), als een écht project met discovery en iteraties en alles? Realistisch zes maand à een jaar.
Ik vroeg het aan Claude,:
Look at this entire project and give me an honest opinion of what making something like this (to this standard) without AI help would have meant in terms of man-days.
Hij denkt dat het meer zou zijn dan ik inschat:
My estimate: about 90–140 working days for you alone, building it to its current standard.
What your experience removes
- Discovery. You are the user, the product owner and the UX specialist. No research, workshops, requirements documents or handovers: the questions get answered in your head, and the testing happens on your phone while you use it.
- Most design iteration. With 20 years of UX, flows and interaction details come out mostly right the first time, and the visual design (palette from the icon, type, dark mode) is a few days rather than a phase.
- Learning Django. Sync, accounts, admin, management commands and deployment are home ground.
- Learning the domain. You know the booklog, its conventions and its history better than anyone could write them down.
What it doesn’t remove
- Writing it. About 12,000 lines of app and server code, plus 2,400 lines of tests. Even at a fast pace, that is months of typing, reading and debugging.
- Unfamiliar browser technology. Camera barcode scanning with a WebAssembly fallback, OCR, straightening a photographed cover, service-worker update races, iOS PWA quirks. Experience shortens this, but it’s still trial and error on real devices.
- The round trip with the booklog. Hugo posts written as git commits, imported back again, with rereads, editions and edits on both sides. Knowing the domain doesn’t prevent edge cases that only real data shows. This is the part most likely to go over.
- Production care. A data-model change rehearsed on a copy of production, migrated, verified and backfilled is slow by nature, however skilled you are.
By area
Area Days The app: lists, progress, filters, three views, bulk edit, offline, two languages, styling 30–45 Scanning, OCR, cover photos 10–15 Catalogue lookups (Open Library, Google Books, Audible) and merging their answers 4–6 Django server: sync with conflict rules, accounts, covers 8–12 The assistant (adapted from existing intake code) 3–5 Two-way sync with the booklog 15–25 Books and editions: the same model in JS and Python, migration, cut-over 12–20 Tests, docs, deploy pipeline, server 8–12 Total ~90–140 What “for me alone” could cut
For an app only you use, some of its current scope is optional: the English interface and translation setup, the mode with no account, the Goodreads-style CSV export for other reading sites, and documentation written for strangers. Dropping those saves roughly 15–25 days. If you also aimed for “good enough for me” instead of the current standard (fewer tests, thinner docs), the total falls to 60–90 days.
A useful core (scan, lists, progress, sync between devices, publishing to the booklog) would take 25–35 days. The rest is the polish and accumulated features that make it pleasant to use every day.
In calendar time
At full time, 90–140 days is 4–7 months. As a side project at 10–15 hours a week, it is 1.5–2.5 years. Most personal projects like this never reach that point: they settle at the useful core and stop there.
Dat klinkt veel erger dan wat ik inschatte, maar de kern staat bijna op het einde: “A useful core […] would take 25–35 days. The rest is the polish and accumulated features that make it pleasant to use every day.” Dat is zo hard harkenbaar: ik zou inderdaad de kern gemaakt hebben, en dan ofwel maanden en jaren geputterd hebben om het helemaal naar mijn goesting te krijgen, ofwel het gewoon zo hebben gelaten en elke dag kwaad geweest zijn op mezelf.
En wat als ik het aan een klein team geef en het als een “echt” project zou beschouwen?
With a four-person team and a full discovery process, my estimate is about 450 person-days (range 380–560), over 7–8 months of calendar time. That is roughly two and a half times my solo estimate. Discovery and design add about 135 days, and the rest of the difference is the cost of four people working together.
Effort by phase and role (person-days)
Total: ~450 person-days (PM: ~104 · UX/UI: ~125 · Front-end: ~117 · Back-end: ~104)
Kick-off — 12 days (PM: 5 · UX/UI: 3 · Front-end: 2 · Back-end: 2)
Goals, stakeholder interviews, project setup.Discovery — 67 days (PM: 28 · UX/UI: 22 · Front-end: 8 · Back-end: 9)
- Field studies (PM: 6, UX/UI: 12): 8–10 readers at home, in shops, logging their reading; recruiting and synthesis.
- Business analysis (PM: 10): book/edition/copy/read model, the existing booklog and boeggn, catalogue APIs, export formats.
- Technical spikes (Front-end: 4, Back-end: 5): barcode and OCR in the browser, PWA on iOS, round trip to Hugo, Open Library / Google / Audible.
- 2–3 user workshops (PM: 4, UX/UI: 6, Front-end: 2, Back-end: 2): journey mapping, card sorting for lists and filters, prioritisation.
- Requirements (PM: 8, UX/UI: 2, Front-end: 2, Back-end: 2): stories, acceptance criteria, non-functional (offline, privacy, sync).
Design — 68 days (PM: 7 · UX/UI: 55 · Front-end: 4 · Back-end: 2)
- Information architecture (UX/UI: 12): flows, wireframes.
- Visual design (UX/UI: 15): icon and palette, dark mode, type, component library.
- Clickable prototypes (UX/UI: 8): scanning, adding, editions, progress.
- Usability tests (PM: 3, UX/UI: 8): two rounds of tests on prototypes (5–6 users each).
- Iterations (UX/UI: 8): updates after testing.
- UX writing (PM: 2, UX/UI: 4): copy in English and Dutch.
- Feasibility reviews (PM: 2, Front-end: 4, Back-end: 2): review by the developers.
Build — 253 days (PM: 50 · UX/UI: 30 · Front-end: 95 · Back-end: 78)
About 10 two-week sprints:
- PM: backlog, ceremonies, acceptance; UX: design QA, edge states.
- Front-end: shell, lists, views, filters, bulk edit, offline, i18n, scanning/OCR/covers, editions.
- Back-end: sync and conflicts, accounts, covers, assistant, booklog import/publish, the shared book model, deploy.
Validation — 19 days (PM: 6 · UX/UI: 10 · Front-end: 2 · Back-end: 1)
Two rounds of tests on real builds, a beta with a diary study, sprint demos.Launch — 31 days (PM: 8 · UX/UI: 5 · Front-end: 6 · Back-end: 12)
Data migration rehearsed and run, the booklog-side changes, user and developer docs.Calendar
- Kick-off: 1 week.
- Discovery: 5–6 weeks.
- Design: about 6 weeks. Back-end foundations start around week 8.
- Build: 20–24 weeks. The front-end developer is the critical path.
- Launch: 2 weeks.
That comes to about 7–8 months. One thing worth knowing if you ever buy this from an agency: they bill for allocation, not effort. With four people booked full-time for 8 months, the invoice is closer to 600–650 days, even though the work itself is about 450. Assuming Belgian agency rates of €700–900 a day (my assumption), the work comes to about €320–400k, and full allocation to about €450–550k.
Things the table hides
- There’s no tester. QA is spread across the developers and the PM. A real team would add a tester, or 10–15% more developer time.
- Coordination is roughly 15% of build time. Ceremonies, handovers, reviews and waiting on each other are already in the build figures. This is the price of parallel work.
- The output would be a different product. Discovery with ten readers would push Folio toward something generic: sign-up, any booklog instead of your Hugo site, fewer idiosyncrasies. It would probably drop things that matter to you, like “kopie” rather than “editie”, rereads in translation as separate pages, and your colour scheme taken from the icon. Folio is this good partly because its one user is also its product owner, and every decision went straight from your head into the code. A team spends much of its discovery budget getting that knowledge out of people’s heads.
- The real discovery happened anyway. It just wasn’t formal. Years of keeping the booklog and boeggn, and the plan document with your answers to its open questions, did the job that field studies and workshops would have done. That’s knowledge a team would have to pay to rebuild.
Dit is optimistischer dan ik het zou zien.
Maar laat het ons toch maar aanvaarden. Dat is honderdduizenden euro’s om iets te maken dat ik op een paar uur hier en daar gemaakt heb. En zeer zeker, als ik mensen de volledige omgeving zou willen geven die ik gebruik, zou ik nog wat extra moeite moeten insteken om het helemaal productieklaar te maken — maar de toepassing zoals ze nu is, is eigenlijk helemaal bruikbaarop uw eigen telefoon (of computer) zonder useraccount. En veiliger dan zowat alles dat ik helemaal zelf zou kunnen gemaakt hebben.
Er zijn hier en dar zeer ongetwijfeld een heel grote groep mensen hard aan het panikeren. En als dat nu nog niet is, dan wel zeer binnenkort.
Een enorm grote stapel skills zijn totaal irrelevant geworden.
Mijn werk voorlopig nog niet: een AI kan niet naast een een gebruiker zitten en observeren wat die doet, een halve blik en een aarzeling of een zucht interpreteren en dat in het aggregaat van een reeks veldstudies synthetiseren tot een coherente visie.
Nog niet.
⁂
De toepassing staat op folio.yusupov.cloud trouwens, voor wie eens wil gaan kijken.